What generative AI needs from people
Large language models and image generators learn from examples, and their output is judged by people. The quality of both decides how a model behaves: what it knows, how it answers, and where it refuses.
That work cannot be automated away. Someone has to write good examples, read the answers, check the facts and say which response is better. This is what our teams do.
What we do
- Training data. Prompts, responses, instructions and conversations, written and curated for your domain.
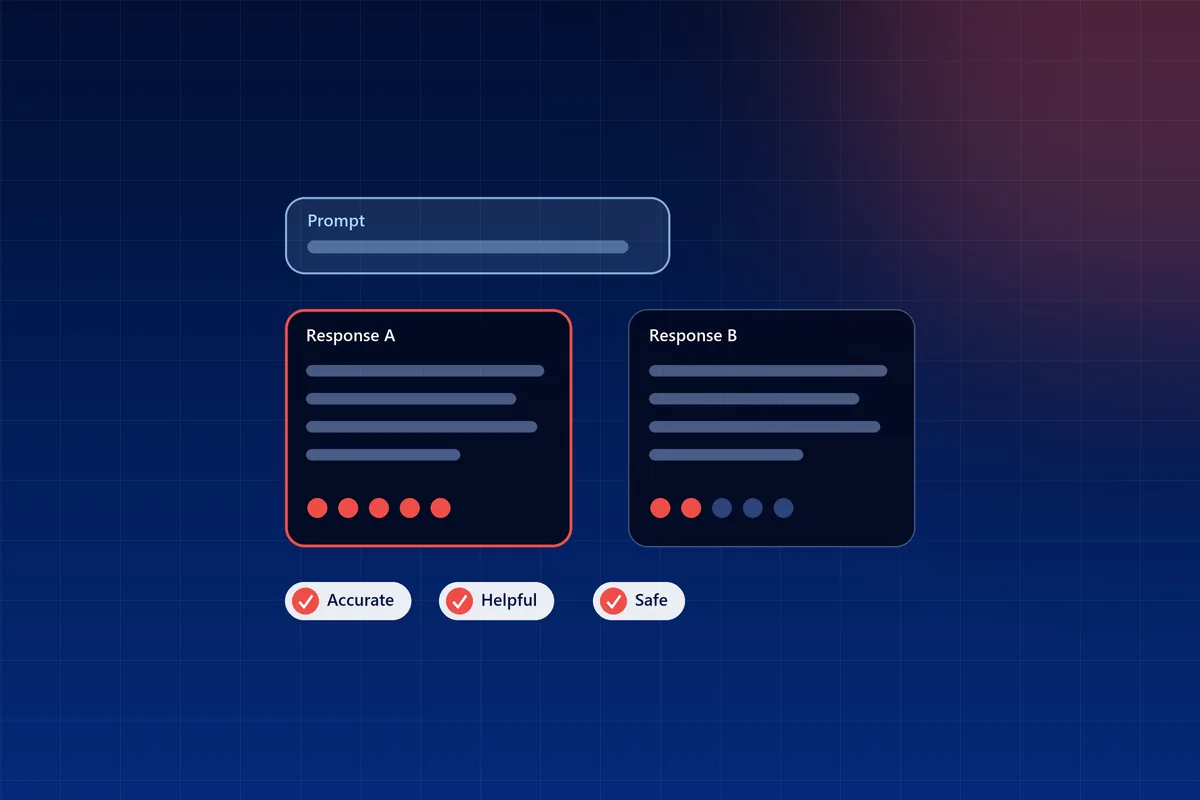
- Response rating and ranking. Scoring single answers against a rubric, or comparing two answers side by side and choosing the better one.
- Fact checking and correction. Verifying claims in model output and rewriting answers that are wrong or incomplete.
- Safety and policy review. Finding harmful, biased or off-policy output, in the same way as our content moderation work. The NIST AI Risk Management Framework describes the kinds of risk reviewers look for.
- Language data. Classification, entities and intent through text annotation, and sentiment analysis.
- Image and text pairs. Captions, image descriptions and ratings of generated images.
- Speech data. Audio to text transcription for voice models.
How a review project runs
- Rubric. We agree what a good answer is: accuracy, helpfulness, tone, safety. Each score gets written examples.
- Calibration. Reviewers score the same sample. Differences are discussed until the scoring agrees.
- Production. Reviewers work to the rubric. A share of items is scored by more than one person, to measure agreement.
- Reporting. You receive scores, reasons and examples in the format you need.
Where it is used
- Fine-tuning a model on domain examples
- Evaluating a model before a release
- Preference data that teaches a model which answer people choose
- Safety testing with difficult and adversarial prompts
- Checking that answers are supported by the retrieved sources
- Search and recommendation relevance
People and languages
Pripton's AWS Marketplace listings describe 500+ trained annotators. We cover more than 15 languages, including French, German, Spanish, Portuguese, Italian, Arabic, Japanese, Mandarin, Russian, Turkish and Hindi, with translation when a dataset has to exist in several of them.
We work across consumer goods, retail, healthcare, banking, legal and coding, so reviewers can be matched to the subject.
Quality you can measure
Our AWS Marketplace listings report 98.5% average accuracy. If a project falls below 96.5% accuracy, we rework it.
Start a project
Human Review Services and NLP Data Labelling Services are available on AWS Marketplace: see the platform page. Or describe your model and what you want reviewed through the contact page.


